

Raon-1
Collection
5 items • Updated • 12
This repository contains the MLX weights of Raon-1 mini preview for Apple silicon.
The weights are quantized to NVFP4.
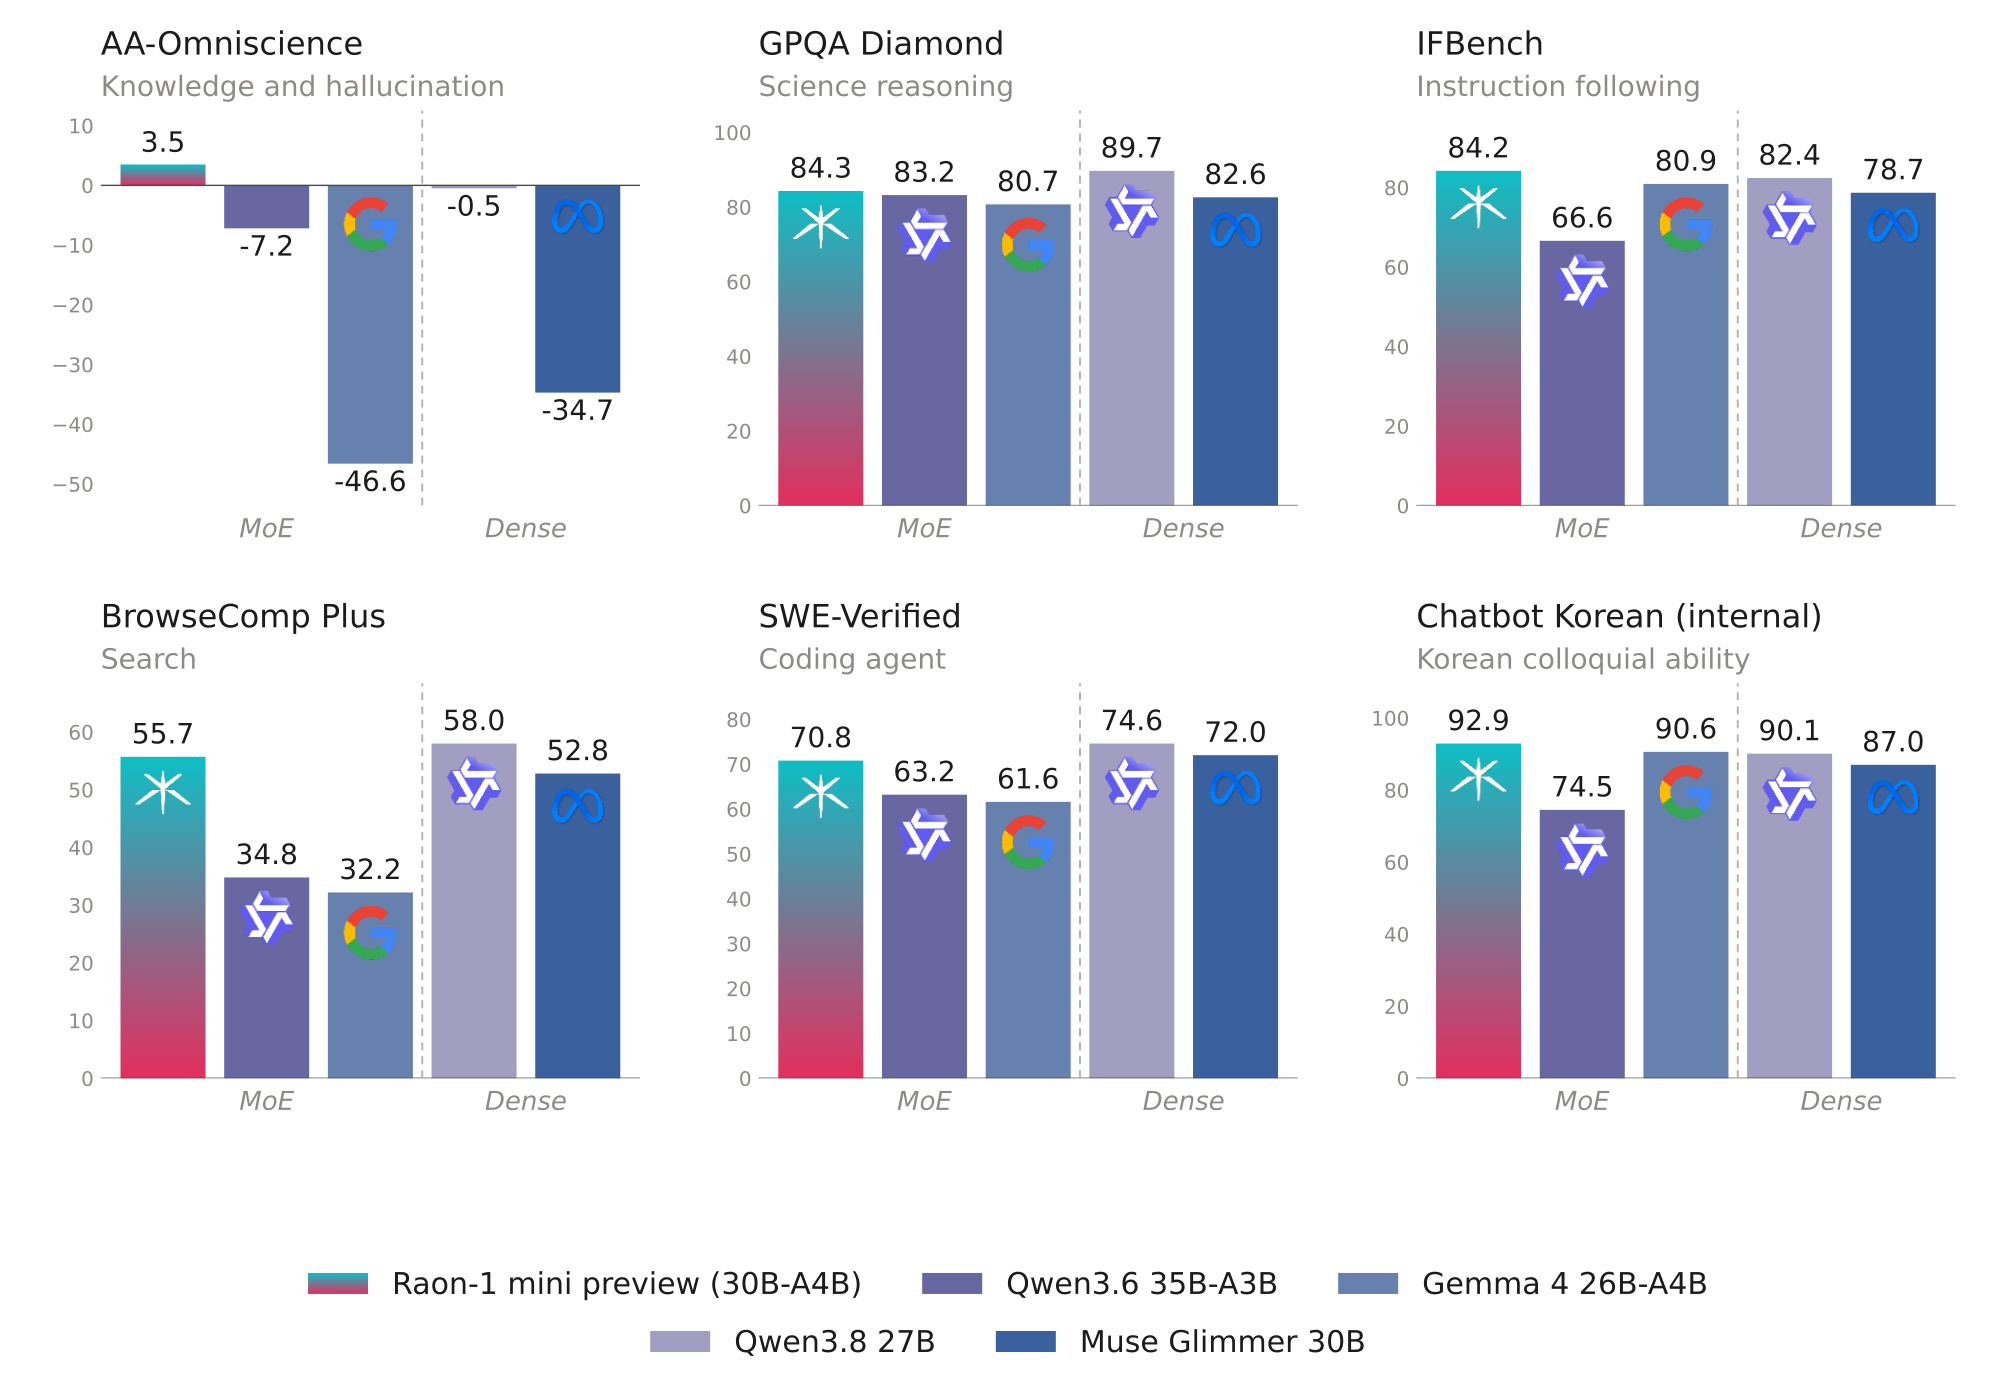
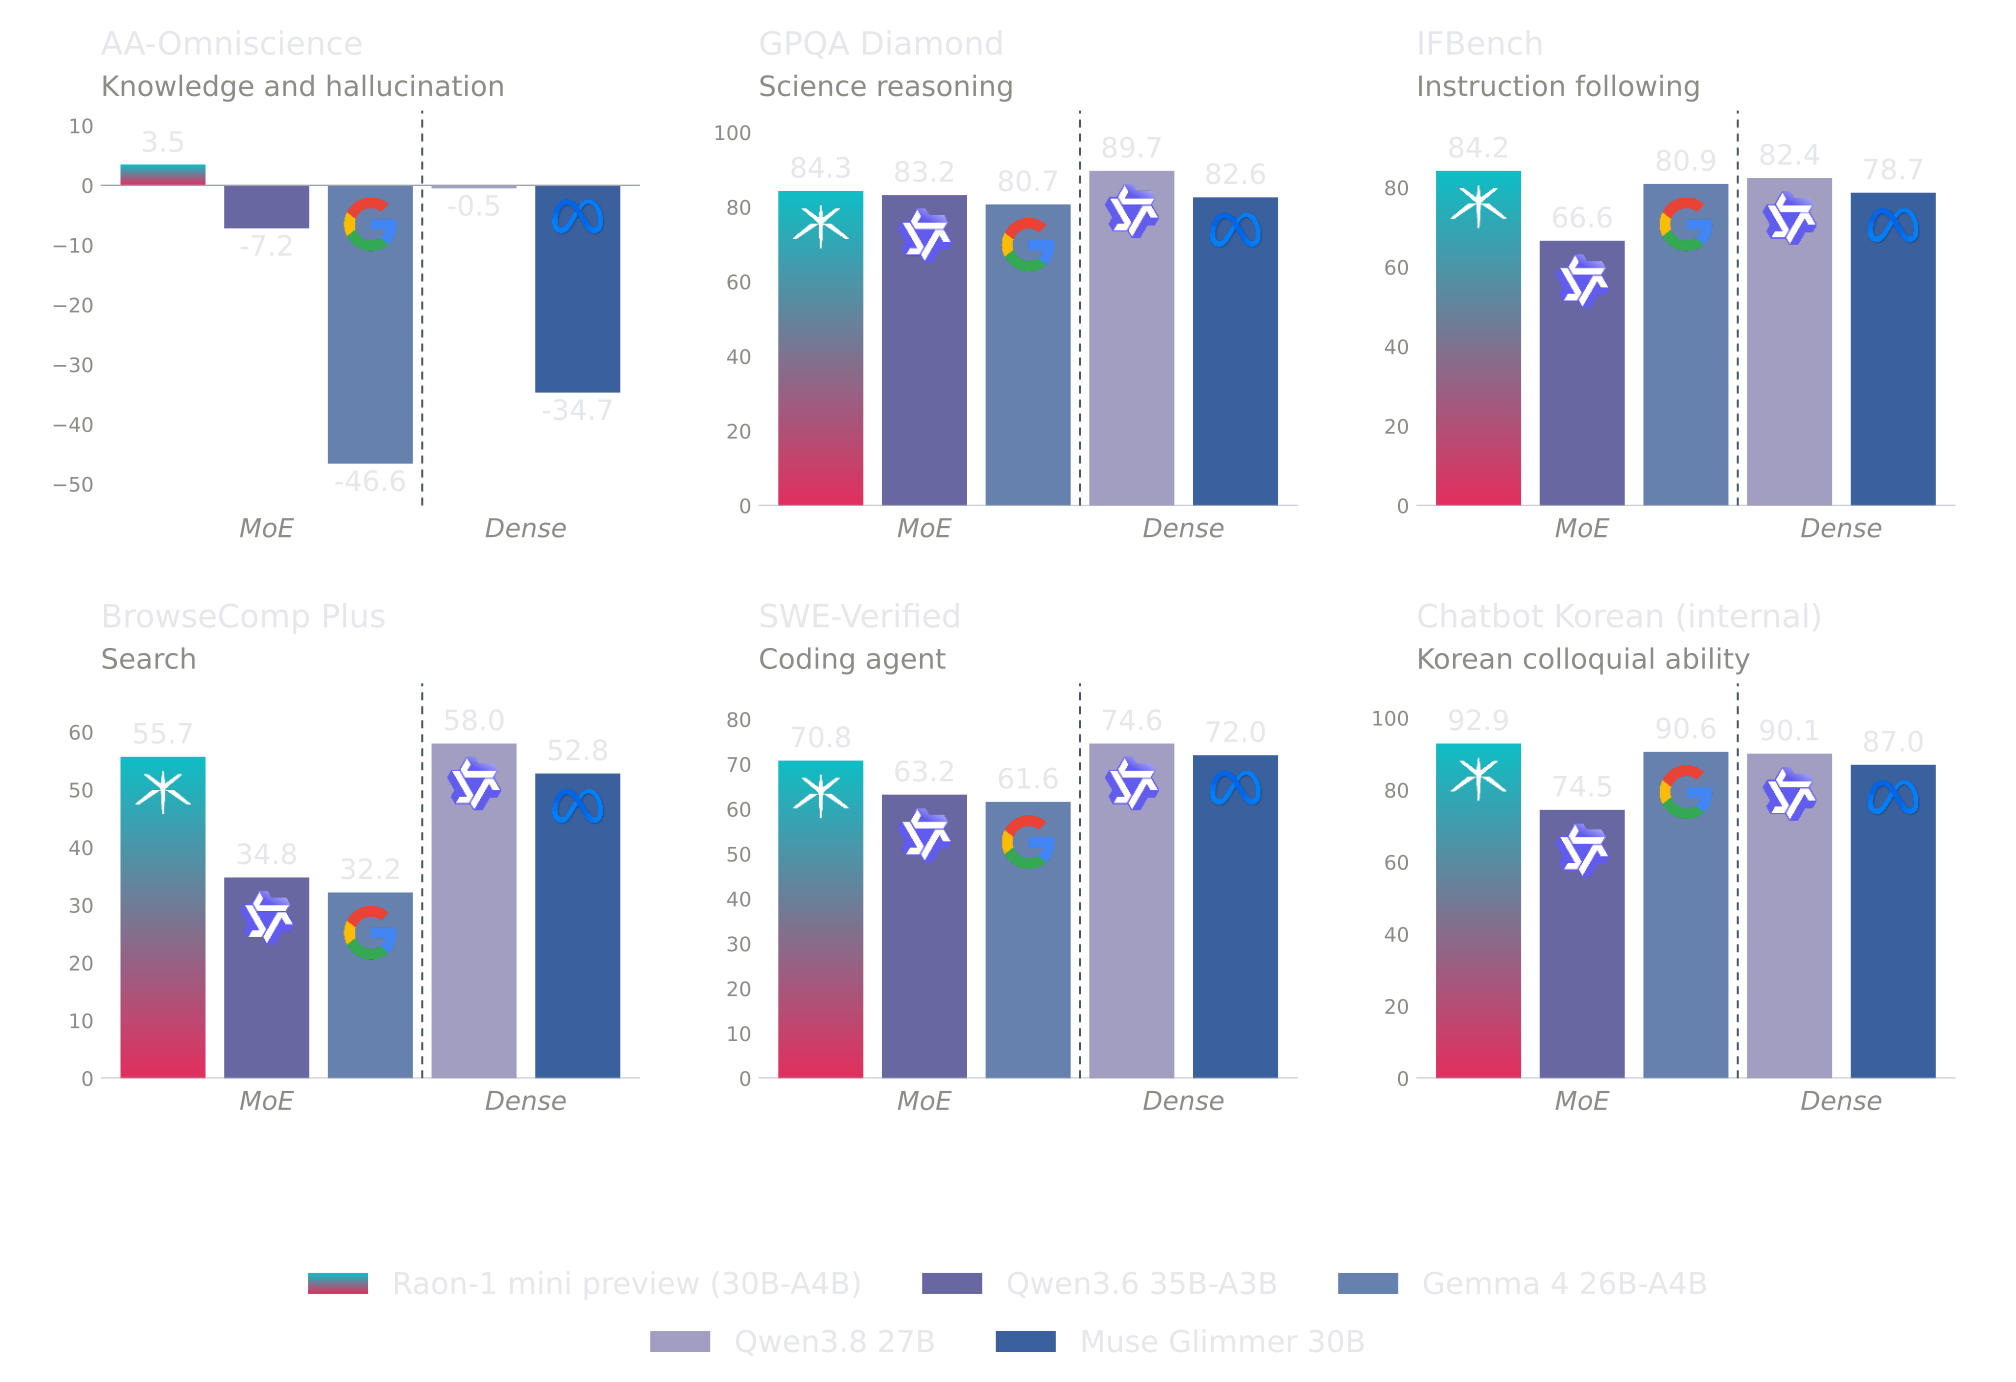
Raon-1 mini is a 30B-A4B Mixture-of-Experts (MoE) language model, designed and trained from scratch by KRAFTON AI. It demonstrates strong capabilities in Korean conversation and agentic tasks. As part of the Raon open model family, it is released under the Apache 2.0 license.
Want to try Raon-1 mini without setting anything up?
Chat with it for free, for a limited time, in the Raon-1 mini playground.
This is a preview release, not a final model. Specs and results may change before the final version.
Raon-1 mini uses a hybrid Mixture-of-Experts (MoE) architecture, consisting of 18 linear attention layers and 7 full attention layers.
| Field | Value |
|---|---|
| Architecture | MoE |
| Total Parameters | 28.8B |
| Activated Parameters | 4.3B |
| Layers | 25 |
| Hidden Size | 2,560 |
| Attention | Hybrid — RDA 3 : Gated MLA 1 |
| Position Encoding | NoPE (no positional encoding) |
| Number of Attention Heads | 40 for both RDA & Gated MLA |
| Attention Head Dimension | 128 for RDA; 192 QK / 128 V, for Gated MLA |
| Query / KV LoRA Rank | 576 / 512, for Gated MLA |
| Number of Experts | 128 |
| Number of Activated Experts | 6 routed + 1 shared |
| Expert Intermediate Size | 1,088 |
| Dense FFN Intermediate Size (first layer) | 12,032 |
| Activation Function | SiTU-GLU |
| Residual Connection | Raon-mHC w/ 4 streams |
| Vocabulary Size | 259,840 |
| LM Head | Untied |
| Context Length | 262,144 tokens |
| Category | Benchmark | MoE | Dense | |||
|---|---|---|---|---|---|---|
| Raon-1 mini preview (30B-A4B) | Qwen3.6-35B-A3B | Gemma 4 26B-A4B | Qwen3.8-27B | Muse Glimmer 30B | ||
| Knowledge | MMLU Pro | 76.5 | 85.9 | 82.9 | 85.7 | 84.0 |
| AA-Omniscience | 3.5 | −7.2 | −46.6 | −0.5 | −34.7 | |
| Reasoning | GPQA Diamond | 84.3 | 83.2 | 80.7 | 89.7 | 82.6 |
| AIME 2026 | 93.3 | 92.9 | 87.1 | 98.8 | 92.9 | |
| HMMT Feb 2026 | 84.1 | 84.5 | 79.9 | 95.8 | 74.6 | |
| Instruction and multi-turn | IFBench | 84.2 | 66.6 | 80.9 | 82.4 | 78.7 |
| MultiChallenge | 59.0 | 58.2 | 58.4 | 63.6 | 63.4 | |
| Coding | LiveCodeBench v6 | 81.6 | 81.2 | 83.4 | 79.3 | 77.4 |
| SciCode | 38.7 | 35.6 | 39.6 | 44.6 | 43.6 | |
| SWE-Verified¹ | 70.8 | 63.2 | 61.6 | 74.6 | 72.0 | |
| Terminal-Bench Lite | 47.0 | 63.3 | 52.0 | 67.0 | 70.7 | |
| Agentic | GDPVal² | 66.0 | 67.4 | 57.5 | 63.5 | 67.3 |
| AutomationBench³ | 29.7 | 24.9 | 36.2 | 58.7 | 32.1 | |
| BrowseComp Plus | 55.7 | 34.8 | 32.2 | 58.0 | 52.8 | |
| BFCL v4 Overall | 59.8 | 64.7 | 65.8 | 72.4 | 51.8 | |
| Long context | AA-LCR | 67.3 | 69.3 | 67.0 | 80.3 | 81.3 |
| GDP.pdf⁴ | 5.8 | 6.6 | 3.6 | 11.2 | 8.4 | |
| Korean conversation | Chatbot Korean (internal)⁵ | 92.9 | 74.5 | 90.6 | 90.1 | 87.0 |
Judge and user simulator: gpt-5.6-luna for all evaluations.
Red = Raon-1 mini preview is best within the MoE group (Raon-1 mini preview, Qwen3.6-35B-A3B, Gemma 4 26B-A4B). Dense models (Qwen3.8-27B, Muse Glimmer 30B) are shown for reference only.
¹ SWE-Verified: evaluated with the mini-SWE-agent harness.
² GDPVal (dataset): metric is a judge score, not Elo.
³ AutomationBench: public split, not the official evaluation set.
⁴ GDP.pdf: official Artificial Analysis (artificialanalysis.ai) text-only version. PDFs are OCR-ed in advance; no image input.
⁵ Chatbot Korean (internal): an internal benchmark measuring Korean colloquial ability in chatbot conversations across diverse situations. Not publicly released.
Raon-1 mini is designed for thinking mode; disabling it is not recommended.
Settings shared by all tasks:
| Setting | Value |
|---|---|
| temperature | 1.0 |
| top_p | 0.95 |
| top_k | 20 |
| repetition_penalty | 1.0 |
| frequency_penalty | 0 |
| min_p | 0 |
| truncate_history_thinking | false |
Settings that depend on the task:
| Task | presence_penalty |
|---|---|
| Coding / math | 0 |
| Everything else (chat, summarization, knowledge Q&A, agents, etc.) | 1.5 |
We release a DFlash2 draft model alongside Raon-1 mini preview to accelerate inference through speculative decoding. In our benchmarks on a single NVIDIA B300, it delivers up to 2.18× higher output throughput than autoregressive decoding. Speedups vary by hardware and workload.
Throughput is measured in output tok/s, with speedup over autoregressive decoding in parentheses. Acceptance length (AL) is the mean number of tokens per verification step, averaged across requests at concurrency 1.
| Benchmark | AL | AR · C=1 | DFlash2 · C=1 | AR · C=8 | DFlash2 · C=8 | AR · C=32 | DFlash2 · C=32 |
|---|---|---|---|---|---|---|---|
| GSM8K | 4.76 | 296.3 | 646.3 (2.18×) | 1,110.4 | 1,836.3 (1.65×) | 1,528.9 | 2,619.3 (1.71×) |
| MATH-500 | 4.43 | 308.0 | 666.6 (2.16×) | 1,496.1 | 2,511.3 (1.68×) | 3,082.5 | 5,166.9 (1.68×) |
| HumanEval | 3.96 | 305.4 | 607.9 (1.99×) | 1,470.8 | 2,269.6 (1.54×) | 2,793.1 | 4,596.4 (1.65×) |
| MBPP | 3.85 | 307.0 | 604.1 (1.97×) | 1,450.6 | 2,197.2 (1.51×) | 2,956.2 | 5,017.9 (1.70×) |
| MT-Bench | 3.24 | 304.9 | 570.2 (1.87×) | 1,477.1 | 2,038.2 (1.38×) | 2,521.3 | 3,935.4 (1.56×) |
Raon-1 mini supports inference with Transformers, vLLM, llama.cpp, and MLX. The examples below show how to run the model locally or launch an OpenAI-compatible server, using thinking mode and the recommended sampling settings above.
The model repositories are gated. Request access once on this page (approval is automatic; it covers every Raon-1 mini preview repository), then log in so the examples below can download them:
pip install -U huggingface_hub
hf auth login
Use Hugging Face Transformers to load Raon-1 mini and generate responses directly in Python.
Install the dependencies:
uv venv --python 3.12 --seed
source .venv/bin/activate

pip install \
    "transformers==5.16.1" \
    "accelerate==1.15.0"
Then run the model:
from transformers import AutoModelForCausalLM, AutoTokenizer

model_id = "KRAFTON/Raon-1-mini-preview"

tokenizer = AutoTokenizer.from_pretrained(
    model_id,
    trust_remote_code=True,
)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    dtype="auto",
    device_map="auto",
    trust_remote_code=True,
)

messages = [
    {"role": "user", "content": "Tell me about KRAFTON AI."}
]
inputs = tokenizer.apply_chat_template(
    messages,
    add_generation_prompt=True,
    tokenize=True,
    return_dict=True,
    return_tensors="pt",
    enable_thinking=True,
    truncate_history_thinking=False,
).to(model.device)

outputs = model.generate(
    **inputs,
    max_new_tokens=32768,
    do_sample=True,
    temperature=1.0,
    top_p=0.95,
    top_k=20,
    min_p=0.0,
    repetition_penalty=1.0,
    presence_penalty=1.5,
)

# The reasoning ends at </think>; the answer follows it.
response = outputs[0][inputs["input_ids"].shape[-1]:].tolist()
think_end = tokenizer.convert_tokens_to_ids("</think>")
split = response.index(think_end) + 1 if think_end in response else 0
reasoning = tokenizer.decode(response[:split], skip_special_tokens=True).strip()
answer = tokenizer.decode(response[split:], skip_special_tokens=True).strip()
print("Reasoning:\n" + reasoning)
print("\nAnswer:\n" + answer)
presence_penalty is applied by the model's remote code, since
Transformers has no built-in presence penalty.
For coding and math, set presence_penalty to 0.0.
Use vLLM to serve Raon-1 mini through an OpenAI-compatible API with tool calling and DFlash2 speculative decoding. Tested on NVIDIA B300.
Install from our fork and start the server:
VLLM_REF="raon-1-mini-preview"

uv venv --python 3.12
source .venv/bin/activate

VLLM_USE_PRECOMPILED=1 uv pip install \
    "vllm @ git+https://github.com/krafton-ai/vllm.git@${VLLM_REF}"

vllm serve KRAFTON/Raon-1-mini-preview \
    --host 127.0.0.1 \
    --port 8000 \
    --served-model-name Raon-1-mini-preview \
    --max-model-len 262144 \
    --max-num-batched-tokens 16384 \
    --max-num-seqs 128 \
    --gpu-memory-utilization 0.85 \
    --kv-cache-dtype fp8_e4m3 \
    --enable-prefix-caching \
    --spec-method dflash \
    --spec-model KRAFTON/Raon-1-mini-preview-dflash2 \
    --spec-tokens 7 \
    --reasoning-parser raon_1 \
    --enable-auto-tool-choice \
    --tool-call-parser raon_1 \
    --default-chat-template-kwargs '{
      "enable_thinking": true,
      "truncate_history_thinking": false
    }'
The first start compiles the model's kernels and takes about 10 minutes;
later starts reuse them.
To serve the NVFP4 checkpoint, replace the model with
KRAFTON/Raon-1-mini-preview-nvfp4 in the same command.
It runs on a single GPU (tensor parallel size 1).
Send a request from another terminal:
curl http://localhost:8000/v1/chat/completions \
    -H "Content-Type: application/json" \
    -d '{
      "model": "Raon-1-mini-preview",
      "messages": [
        {
          "role": "user",
          "content": "Tell me about KRAFTON AI."
        }
      ],
      "max_tokens": 32768,
      "temperature": 1.0,
      "top_p": 0.95,
      "top_k": 20,
      "min_p": 0.0,
      "repetition_penalty": 1.0,
      "frequency_penalty": 0.0,
      "presence_penalty": 1.5,
      "chat_template_kwargs": {
        "enable_thinking": true,
        "truncate_history_thinking": false
      }
    }'
Reasoning is returned in message.reasoning;
the answer is in message.content.
For coding and math, set presence_penalty to 0.
Use llama.cpp to run the GGUF checkpoint locally in a terminal or through an OpenAI-compatible API, with optional DFlash2 speculative decoding.
Checkpoint: KRAFTON/Raon-1-mini-preview-gguf
Build from our branch; upstream support is pending. On Windows, see the build guide.
git clone -b raon-1-mini-preview \
    https://github.com/krafton-ai/llama.cpp
cd llama.cpp

# Omit -DGGML_CUDA=ON on Apple silicon.
cmake -B build -DGGML_CUDA=ON
cmake --build build --config Release -j
Start a terminal chat. The model downloads automatically.
./build/bin/llama-cli \
    -hf KRAFTON/Raon-1-mini-preview-gguf:Q4_K_M \
    --ctx-size 262144 \
    --n-predict 32768 \
    --temp 1.0 \
    --top-p 0.95 \
    --top-k 20 \
    --min-p 0.0 \
    --repeat-penalty 1.0 \
    --frequency-penalty 0.0 \
    --presence-penalty 1.5 \
    --reasoning on \
    --chat-template-kwargs '{
      "enable_thinking": true,
      "truncate_history_thinking": false
    }'
Or start an OpenAI-compatible server:
./build/bin/llama-server \
    -hf KRAFTON/Raon-1-mini-preview-gguf:Q4_K_M \
    --host 127.0.0.1 \
    --port 8000 \
    --alias Raon-1-mini-preview \
    --ctx-size 262144 \
    --parallel 1 \
    --n-predict 32768 \
    --temp 1.0 \
    --top-p 0.95 \
    --top-k 20 \
    --min-p 0.0 \
    --repeat-penalty 1.0 \
    --frequency-penalty 0.0 \
    --presence-penalty 1.5 \
    --reasoning on \
    --chat-template-kwargs '{
      "enable_thinking": true,
      "truncate_history_thinking": false
    }'
For coding and math, use --presence-penalty 0.
For DFlash2 speculative decoding, append these options to either
command with a trailing \ on the preceding line.
The draft model downloads automatically.
    --spec-type draft-dflash \
    --spec-draft-n-max 7 \
    --spec-draft-sampling probabilistic
Send a request from another terminal:
curl http://localhost:8000/v1/chat/completions \
    -H "Content-Type: application/json" \
    -d '{
      "model": "Raon-1-mini-preview",
      "messages": [
        {
          "role": "user",
          "content": "Tell me about KRAFTON AI."
        }
      ],
      "max_tokens": 32768,
      "temperature": 1.0,
      "top_p": 0.95,
      "top_k": 20,
      "min_p": 0.0,
      "repeat_penalty": 1.0,
      "frequency_penalty": 0.0,
      "presence_penalty": 1.5,
      "chat_template_kwargs": {
        "enable_thinking": true,
        "truncate_history_thinking": false
      }
    }'
Reasoning is returned in message.reasoning_content;
the answer is in message.content.
For coding and math, set presence_penalty to 0.
Use MLX to run Raon-1 mini locally on Apple silicon, either directly in Python or through an OpenAI-compatible API.
Checkpoint: KRAFTON/Raon-1-mini-preview-mlx
Install the dependencies with Python 3.11+ (the macOS system python3 is older, so create the environment with uv):
uv venv --python 3.12 --seed
source .venv/bin/activate

python -m pip install \
    "mlx==0.32.4" \
    "mlx-lm==0.32.2" \
    "transformers==5.20.1"
Run in Python:
from mlx_lm import load, generate
from mlx_lm.sample_utils import (
    make_logits_processors,
    make_sampler,
)

model, tokenizer = load(
    "KRAFTON/Raon-1-mini-preview-mlx",
    trust_remote_code=True,
)

messages = [
    {"role": "user", "content": "Tell me about KRAFTON AI."}
]
prompt = tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True,
    enable_thinking=True,
    truncate_history_thinking=False,
)

response = generate(
    model,
    tokenizer,
    prompt=prompt,
    max_tokens=32768,
    sampler=make_sampler(
        temp=1.0,
        top_p=0.95,
        top_k=20,
        min_p=0.0,
    ),
    logits_processors=make_logits_processors(
        repetition_penalty=1.0,
        frequency_penalty=0.0,
        presence_penalty=1.5,
    ),
)
print(response)
Loading the model prints a [transformers] You are using a model of type raon1_mini to instantiate a model of type ...
warning. It is expected and can be ignored.
Or start an OpenAI-compatible server:
python -m mlx_lm server \
    --model KRAFTON/Raon-1-mini-preview-mlx \
    --trust-remote-code \
    --host 127.0.0.1 \
    --port 8000 \
    --max-tokens 32768 \
    --chat-template-args '{
      "enable_thinking": true,
      "truncate_history_thinking": false
    }' \
    --decode-concurrency 2 \
    --prompt-concurrency 2
Send a request from another terminal:
curl http://localhost:8000/v1/chat/completions \
    -H "Content-Type: application/json" \
    -d '{
      "model": "default_model",
      "messages": [
        {
          "role": "user",
          "content": "Tell me about KRAFTON AI."
        }
      ],
      "max_tokens": 32768,
      "temperature": 1.0,
      "top_p": 0.95,
      "top_k": 20,
      "min_p": 0.0,
      "repetition_penalty": 1.0,
      "frequency_penalty": 0.0,
      "presence_penalty": 1.5,
      "chat_template_kwargs": {
        "enable_thinking": true,
        "truncate_history_thinking": false
      }
    }'
Use http://localhost:8000/v1 as the base URL
and default_model as the model name.
mlx_lm server returns the reasoning in the reasoning field of the message and the answer in content.
For coding and math, set presence_penalty to 0.
Faster generation with DFlash2 (speculative decoding). raon_mlx_model.py can also run the bundled DFlash2 draft
model (dflash2/). Download the repository and run the commands from its folder:
hf download KRAFTON/Raon-1-mini-preview-mlx --local-dir Raon-1-mini-preview-mlx
cd Raon-1-mini-preview-mlx
DFlash2 on (default):
python raon_mlx_model.py generate \
    --prompt "Tell me about KRAFTON AI." \
    --max-tokens 32768 \
    --temp 1.0 --top-p 0.95 --top-k 20 --presence-penalty 1.5
DFlash2 off (plain MLX-LM generation): add --no-dflash.
python raon_mlx_model.py generate --no-dflash \
    --prompt "Tell me about KRAFTON AI." \
    --max-tokens 32768 \
    --temp 1.0 --top-p 0.95 --top-k 20 --presence-penalty 1.5
Or start an OpenAI-compatible server (/v1/chat/completions, streaming, /v1/models), with DFlash2 on or off:
python raon_mlx_model.py serve --host 127.0.0.1 --port 8000              # DFlash2 on
python raon_mlx_model.py serve --host 127.0.0.1 --port 8000 --no-dflash  # DFlash2 off
The server reads temperature, top_p, top_k, presence_penalty, seed, max_tokens, stop, stream and
chat_template_kwargs from each request, and its defaults are temperature 1.0, top-p 0.95, top-k 20 and
presence penalty 0. Thinking is on unless a request sets "enable_thinking": false. The reasoning is returned in
reasoning_content and the answer in content. Tool calling is not supported by this server; use mlx_lm server
above for it.
Options for both commands:
--no-dflash: turn DFlash2 off (plain MLX-LM generation).--draft-tokens: draft length. The default is 5, raised to 7 automatically while acceptance is high.--draft: another draft folder or repo id.--max-tokens, --temp, --top-p, --top-k, --presence-penalty, --seed.generate also takes --system and --no-thinking; serve takes --host, --port, --model-id and
--no-thinking, which changes the default for requests that do not set it.
DFlash2 needs mlx==0.32.4 and mlx-lm 0.32.x as installed above. With other versions it prints a warning and
generates without the draft. While it is on, the module wraps mx.quantized_matmul and a few of its own layer
methods in the running process; outside the draft check they call the original code.
The presence penalty counts all generated tokens, as in vLLM. MLX-LM's penalty, used with --no-dflash, counts
the last 20 tokens including the prompt.
The draft adds about 1 GB of memory.
Quick option guide. These options apply to the bundled raon_mlx_model.py commands above:
--no-dflash to turn it off. Speed depends on how many draft tokens the model accepts.RAON_HEAD_MODE=on to enable it (off disables it). It automatically uses greedy selection for --temp 0 (or less) and sampling for a positive temperature; the server uses each request's temperature. This is approximate and can change the output. DFlash2 draft verification always uses the full output head.RAON_DFLASH2_OVERLAP=0 to disable overlapping CPU preparation with GPU work. This changes scheduling, not the sampling mode; the speed effect depends on the workload.For example, enable the two-stage head with DFlash2 and greedy decoding:
RAON_HEAD_MODE=on python raon_mlx_model.py generate \
    --prompt "Tell me about KRAFTON AI." --max-tokens 1024 --temp 0
Add --no-dflash to use the same head option without DFlash2. The included
head_stage1_a2g64gm.safetensors adds about 208 MB; a missing or invalid file causes a warning and fallback
to the full head. Direct native mlx_lm.generate calls use the full head.
Raon-1 mini preview can be used with agent harnesses such as Hermes Agent, Pi, and OpenCode through an OpenAI-compatible API. The examples below assume an endpoint at http://localhost:8000/v1 with the model ID Raon-1-mini-preview. Adjust these settings to match your server, ensuring that tool calling and reasoning are properly supported.
With MLX, use
KRAFTON/Raon-1-mini-preview-mlxas the model ID instead ofRaon-1-mini-preview;mlx_lm serverloads the model named in each request.
Register Raon-1 mini preview as a custom OpenAI-compatible model in ~/.hermes/config.yaml:
model:
  provider: custom
  default: Raon-1-mini-preview
  base_url: http://localhost:8000/v1
  api_key: dummy
Hermes automatically detects the context window from the server when supported. If detection fails, add context_length: 262144 under model:. Replace dummy with your API key if the endpoint requires authentication.
Register Raon-1 mini preview as a custom provider in ~/.pi/agent/models.json:
{
  "providers": {
    "raon": {
      "baseUrl": "http://localhost:8000/v1",
      "api": "openai-completions",
      "apiKey": "dummy",
      "models": [
        {
          "id": "Raon-1-mini-preview",
          "name": "Raon-1 mini preview",
          "reasoning": true,
          "contextWindow": 262144,
          "maxTokens": 32768
        }
      ]
    }
  }
}
Select the model using /model inside a session, or launch Pi with --model raon/Raon-1-mini-preview. Replace dummy with your API key if the endpoint requires authentication.
Register Raon-1 mini preview as a custom OpenAI-compatible provider in ~/.config/opencode/opencode.json (or opencode.json in your project root):
{
  "$schema": "https://opencode.ai/config.json",
  "provider": {
    "raon": {
      "npm": "@ai-sdk/openai-compatible",
      "name": "Raon",
      "options": {
        "baseURL": "http://localhost:8000/v1"
      },
      "models": {
        "Raon-1-mini-preview": {
          "name": "Raon-1 mini preview",
          "limit": {
            "context": 262144,
            "output": 32768
          }
        }
      }
    }
  },
  "model": "raon/Raon-1-mini-preview"
}
The model field sets Raon-1 mini preview as the default model. You can also select it interactively using /models. If the endpoint requires authentication, configure an API key under options or use OpenCode's authentication settings.
For all three agent harnesses, the configured context window and maximum output tokens should not exceed the limits supported by the serving backend.
Raon-1 mini preview is an open-weight model. Access is granted on request.
You can also try it in the Raon-1 mini playground, free for a limited time.
The Raon model, including its model weights, configuration files, and other model components made available for download through this repository, is licensed under the Apache License, Version 2.0. Subject to that license, you may download, use, modify, and redistribute the model and its weights, including for commercial purposes.
Krafton and its licensors retain ownership of their respective intellectual property. The Apache License grants the rights stated in that license and does not transfer ownership. Rights in third-party materials remain subject to their applicable terms.
The Apache License does not extend to Krafton’s proprietary training datasets, training methodologies, undistributed software, hosted API, playground, or other proprietary materials not included in this repository.
Krafton also makes Raon available through its hosted API and playground service (“RAON Service”). The Raon Service is not licensed under Apache 2.0. Access to and use of the Raon Service is governed by separate Hosted Access Terms and Conditions that are provided before access to the service is granted. The Hosted Access Terms and Conditions govern, among other things, permitted service use, suspension, termination, and Krafton’s right to charge fees in the future.
Quantized
Base model
KRAFTON/Raon-1-mini-preview